500+ models on tap
GPT, Claude, Gemini, Grok, DeepSeek, Llama, Mistral and hundreds more, all in the same comparison.


Send one prompt to two or more models and read the answers side by side. Blind mode hides names until you pick a winner. Each model bills its own cost.
Send one prompt to two or more models and read the answers side by side. Blind mode hides names until you pick a winner. Each model bills its own cost.
Send one prompt to two or more of the 500+ models and read the answers side by side. Pick them yourself, or go blind and let the answers compete without names.
Krater pricing · AI model directory · AI Image Generator and Photo Editor
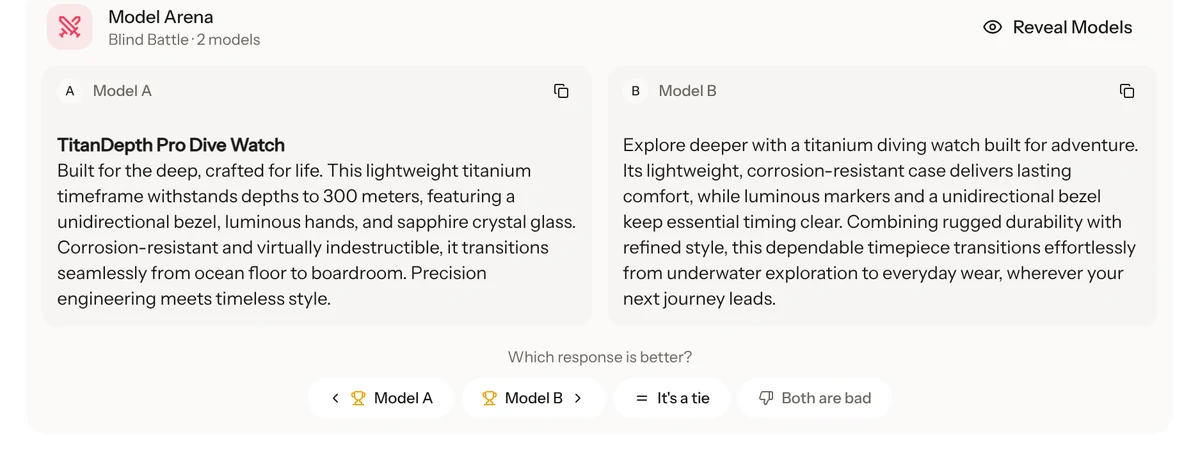
Write a 50 word product description for a titanium diving watch
Blind mode, 2 models · 10 credits
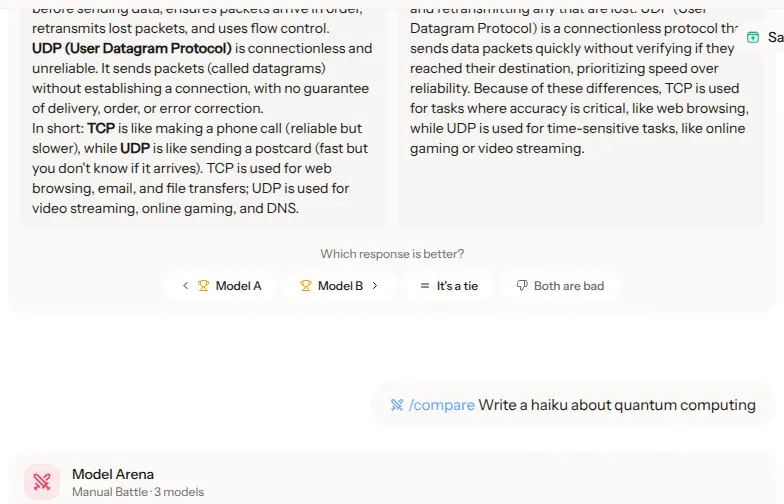
Explain the difference between TCP and UDP in 3 sentences
Blind mode, 2 models · 1 credit
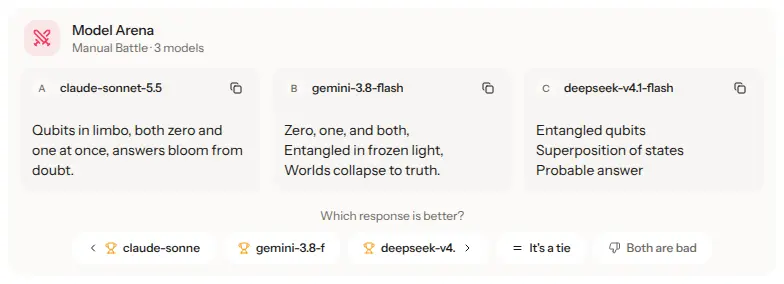
Write a haiku about quantum computing
Manual mode: Claude Sonnet 5.5, Gemini 3.8 Flash, DeepSeek V4.1 Flash · 1 credit
GPT, Claude, Gemini, Grok, DeepSeek, Llama, Mistral and hundreds more, all in the same comparison.
Every model answers the same prompt and the outputs sit next to each other, so differences are obvious at a glance.
Hide the model names until you pick a winner. Kills the brand bias that makes benchmark arguments useless.
Choose exactly which models face off, from frontier flagships to cheap workhorses.
Each model bills its own normal token cost, about 6 credits per model on a typical prompt. Compare three models, pay for three.
You judge actual answers to your actual prompt, not an aggregate benchmark someone else ran on a task you do not care about.
The task you actually care about: a coding problem, a tricky email, a reasoning puzzle.
Choose the contenders yourself or let blind mode hide names so the answers compete clean.
Every answer renders in its own column. Speed, tone and correctness compare instantly.
The model that earned it becomes your pick for the follow-ups. Costs stay per-model.
Run your five most common prompts across the flagships once, then stop wondering.
See which model handles your prompt style before you build a workflow around it.
Same bug, three explanations. The clearest one wins.
Compare drafts on the same brief and keep the voice that fits.
Cross-check an answer across models instead of trusting one.
A model that wins your haiku test might lose your code review. Run two or three prompts that match your real workload before deciding.
A flagship costs more per comparison than a mini. Comparing four premium models on a long prompt is a real spend, so check the estimate first.
Names stay hidden until you pick a winner. That is the point: if you already know which answer you want to win, do not go blind.
Each comparison bills the models it runs at their normal token cost, about 6 credits per model. Pro starts at $20 per month.
Two or more per run, from the 500+ models on Krater. Practical sweet spot is two to four, so the answers stay readable side by side.
The answers show up without model names. You pick the best answer first, then see which model wrote it, so brand preference cannot rig the result.
/compare is for chat models. For image models, run the same prompt in /image with different models selected, or browse the model directory for pricing.
All 500+ models with capabilities and credit pricing.
A head-to-head breakdown of Anthropic's two tiers.
Cited answers when you need sources, not opinions.
Check which model wrote a given text.